How Much Do Coding Agents Read Before Your Prompt? pi 1.4K, Codex 6.4K, Claude Code 15.8K Tokens
First-request prompt size and processing time for three agents, read from llama-server logs. On a 6GB laptop, Claude Code takes 8.6x longer than pi just to read its own prompt.
Numbers
Same llama-server (LFM2.5-24B-A2B Q4_0, -c 32768, RTX 3060 Laptop 6GB). This is the prompt eval line for each agent's first request:
| Agent | Prompt tokens | Time | Share of 32K |
|---|---|---|---|
| pi | 1,442 | 5.7 s | 4% |
| pi (trimmed) | 775 | — | 2% |
| Codex | 6,429 | 18.6 s | 20% |
| Claude Code | ~15,800 | 48.8 s | 48% |
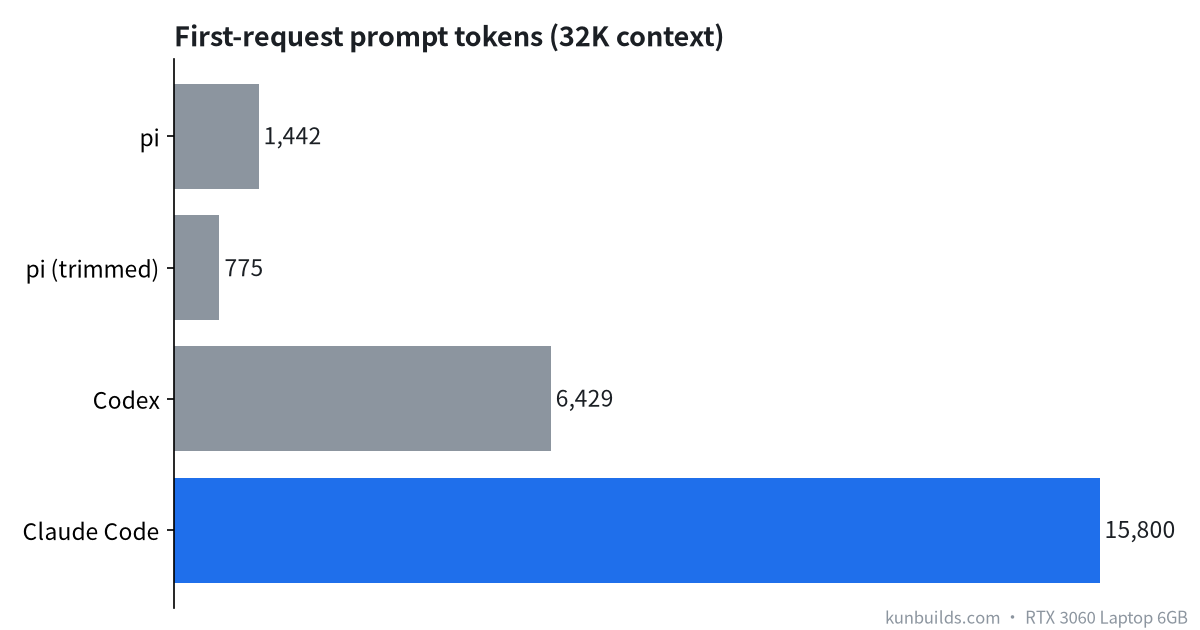
These tokens go out before your question even arrives: the system prompt, tool descriptions and environment info.
Why it matters locally
Cloud models have hundreds of thousands of tokens of context and read 15K tokens in seconds. A small local GPU is different:
- Time: a 6GB laptop prefills a few hundred tokens per second, so every new session starts with a wait of tens of seconds.
- Space: with half of 32K gone, what's left has to hold code, tool output and the conversation. In our runs, Claude Code failed twice with
Prompt is too long, and compaction failed too.
Can you trim it?
pi lets you edit its system prompt. We cut it to about 750 tokens and enabled only the read/edit/bash tools. It still passed all 12 tasks at about the same speed.
How we read the numbers
These are the first prompt eval lines of each group's first run. llama.cpp caches shared prefixes, so later runs of the same agent count only new tokens and look smaller (e.g. Codex shows 394 and 516).