KUN Field Notes
How far can a 6 GB-VRAM laptop push local LLMs?
Every video has a companion write-up with the exact commands, flags, hardware and raw results.
Latest video

24B on a 6GB laptop: tune -ncmoe, three tasks all pass
Most popular
A 35B MoE on 6 GB of VRAM? 64 GB of RAM Made It Work
With enough system RAM, a 35B-class MoE model can be practically usable with 6 GB of VRAM, provided its expert weights stay on the CPU.
24B on a 6GB laptop: tune -ncmoe, three tasks all pass
On an RTX 3060 Laptop (6GB) with 64GB RAM, Liquid AI LFM2.5-24B-A2B (Q4_0) runs locally. Default -ncmoe 40 uses ~1.3GB VRAM; -ncmoe 30 is faster end-to-end and still passes all three tasks—including the bookkeeping case a 35B run once failed. Thinking mode will not stay off.
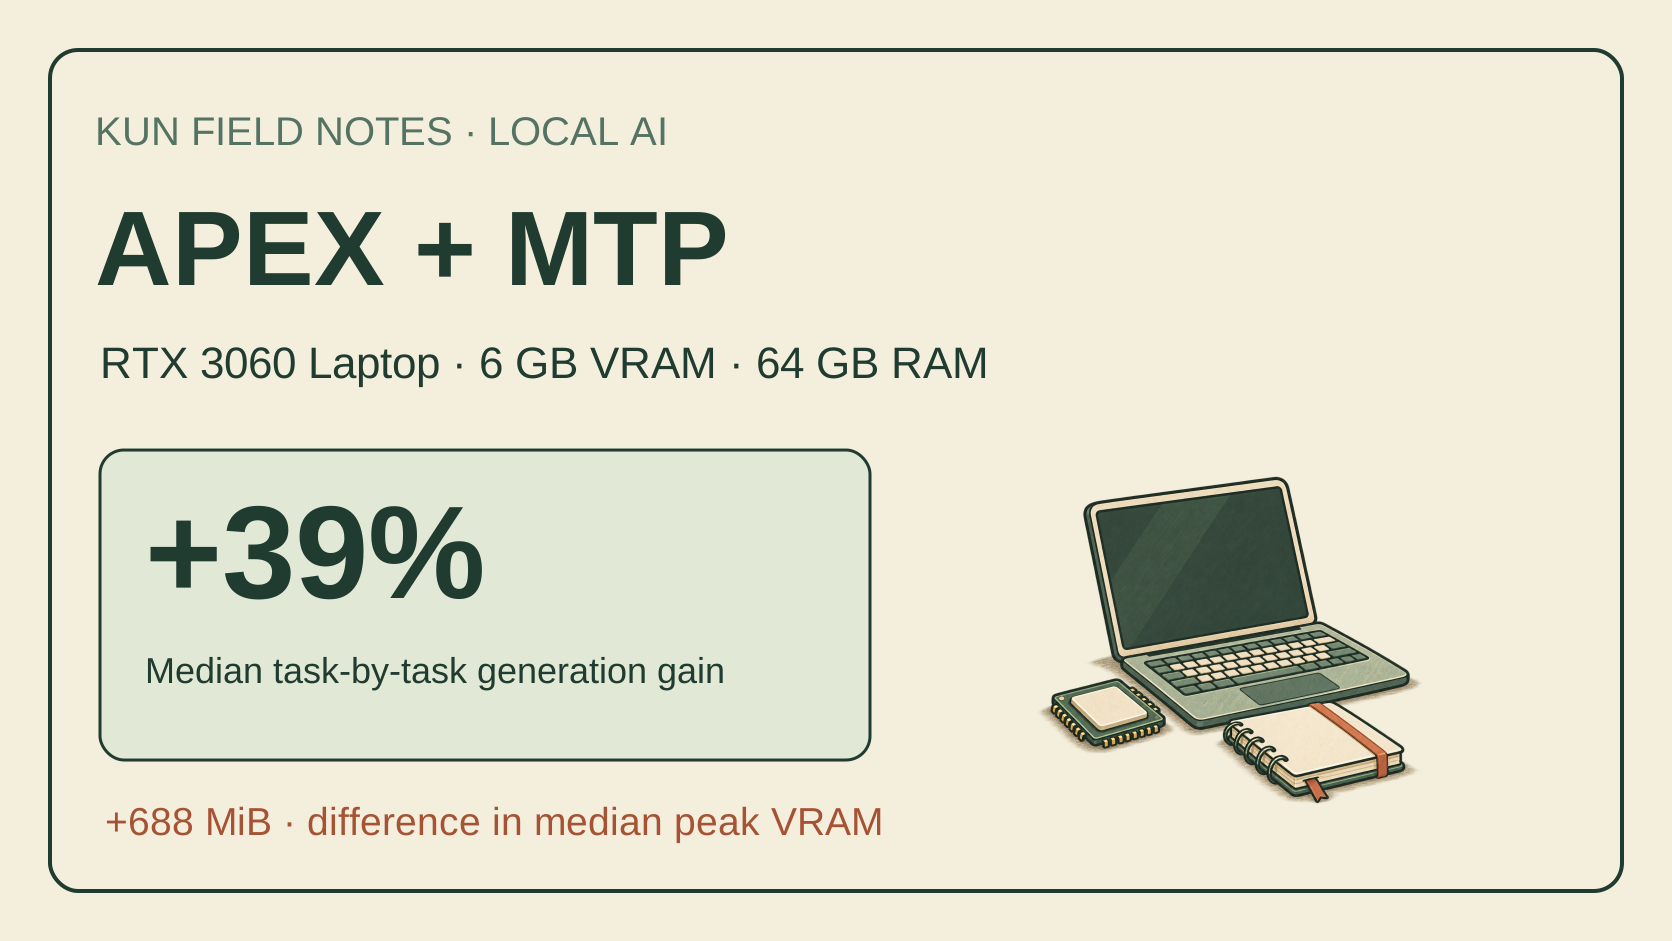
APEX + MTP on a 6 GB laptop: a 39% median generation gain, at what cost?
Across 12 tasks using identical APEX weights, MTP gave a 39% median task-by-task generation-speed gain on my RTX 3060 Laptop (6 GB VRAM, 64 GB RAM). Median peak VRAM rose by 688 MiB; changed answers and retrieval failures are included below.
Latest articles
All articles125B on a 6GB Laptop GPU: Strata 28–34 tok/s vs llama.cpp ~12, but Strata Almost Didn't Run
Qwen3.8 Flash Next (125B, Q2_0) on an RTX 3060 Laptop with 6GB of VRAM and 64GB of RAM. Strata chats at 28–34 tok/s, more than twice llama.cpp, and halves time to first token on a 4K document. But its default config was 383MiB short on VRAM, and it only ran with the MTP draft layer off and 8K context. llama.cpp is slower but still runs 32K.
What Runs on 6GB VRAM? Our Tested List of Local Models (Updated)
Language, image and world models we've actually run on one RTX 3060 Laptop 6GB with 64GB RAM. Every row links to the full test, and only models we ran ourselves are listed.
How Much Do Coding Agents Read Before Your Prompt? pi 1.4K, Codex 6.4K, Claude Code 15.8K Tokens
First-request prompt size and processing time for three agents, read from llama-server logs. On a 6GB laptop, Claude Code takes 8.6x longer than pi just to read its own prompt.
Like hands-on tests you can reproduce?
New videos land on YouTube first; the notes follow here.