24B on a 6GB laptop: tune -ncmoe, three tasks all pass
On an RTX 3060 Laptop (6GB) with 64GB RAM, Liquid AI LFM2.5-24B-A2B (Q4_0) runs locally. Default -ncmoe 40 uses ~1.3GB VRAM; -ncmoe 30 is faster end-to-end and still passes all three tasks—including the bookkeeping case a 35B run once failed. Thinking mode will not stay off.
Verdict
Runs when:64 GB system RAM, llama.cpp commit 9655061, weights LFM2.5-24B-A2B-QAD-Q4_0.gguf. Primary knobs: `-ngl 99 -ncmoe 30` (baseline `-ncmoe 40`).
Main limits
- Reasoning cannot be disabled on this commit/template: thinkoff preflight still emits reasoning; first content often waits 2–3 minutes.
- llama-bench rates exclude tokenisation and sampling — not end-to-end chat speed.
- Validated only on this 6GB laptop + 64GB RAM machine.
Experiment
| Hardware | NVIDIA GeForce RTX 3060 Laptop GPU · 6 GB · laptop · CC 8.6 |
|---|---|
| CPU / RAM | 12th Gen Intel(R) Core(TM) i7-12700H · 64 GB |
| Model | LFM2.5-24B-A2B · Q4_0 · moe |
| Framework | llama.cpp · 9655061 |
| Tested | 2026-10-14T18:00:00+08:00 |
Parameter explorer
Switch between measured combinations only. Unmeasured ones show “Not tested” — we never interpolate and keep the tested label.
Tested here run_id: LFM-030
| run_id | -ngl | -ncmoe | Context depth | Generation (t/s) | Prompt (t/s) | VRAM (model) (MiB) | Wall clock (s) |
|---|---|---|---|---|---|---|---|
| LFM-030 | 99 | 30 | default | 29.47 | 180.7 | 4491 | 40 |
Video
Result: 3/3 tasks pass, including the one 35B got wrong
On a laptop with an NVIDIA GeForce RTX 3060 Laptop GPU (6 GB) and 64 GB RAM, LFM2.5-24B-A2B (Q4_0) at -ncmoe 30 passed all three real tasks: a coding fix (CODE-001), a UTC bookkeeping rollup (DATA-004), and long-manual QA (DOC-001).
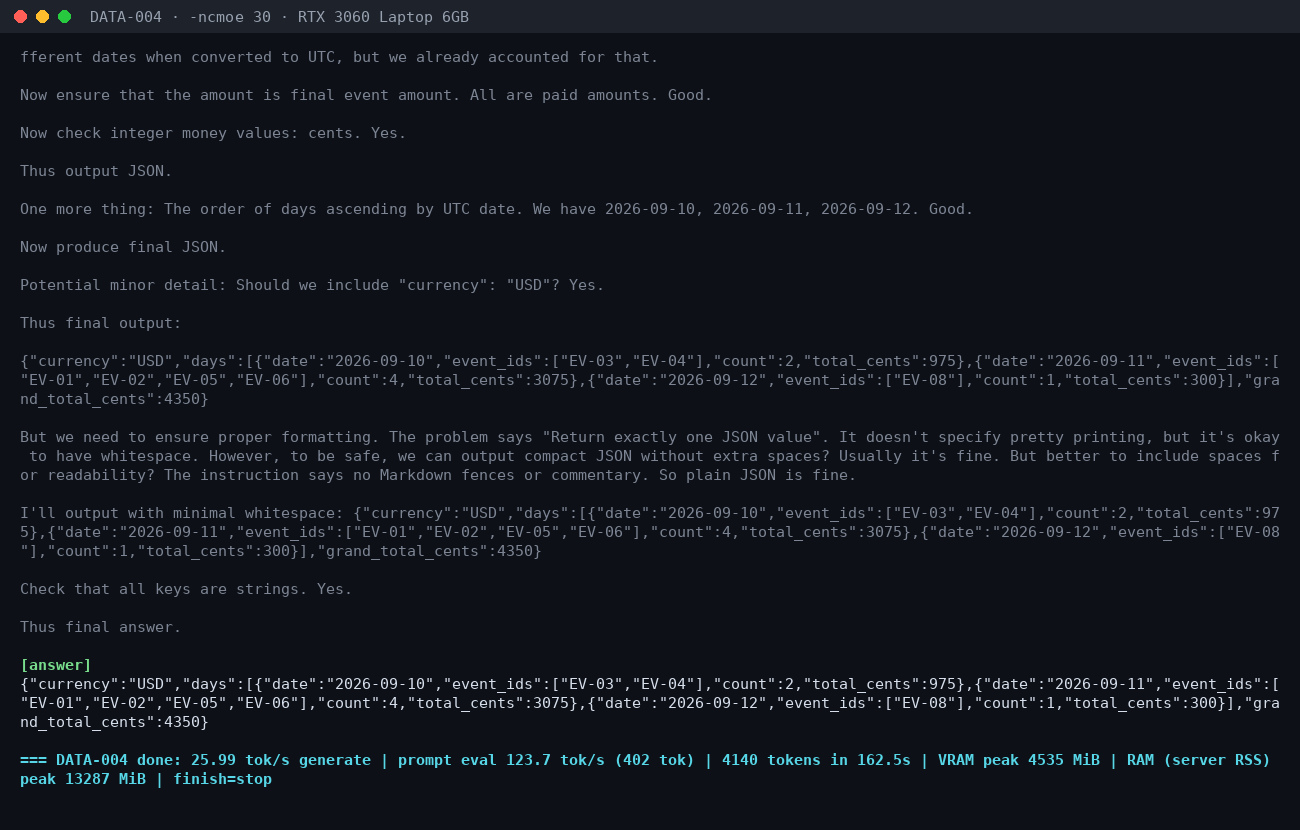
DATA-004 is the task our earlier 35B run failed. The 24B got grand_total_cents: 4350 right.
Live: one task from start to answer
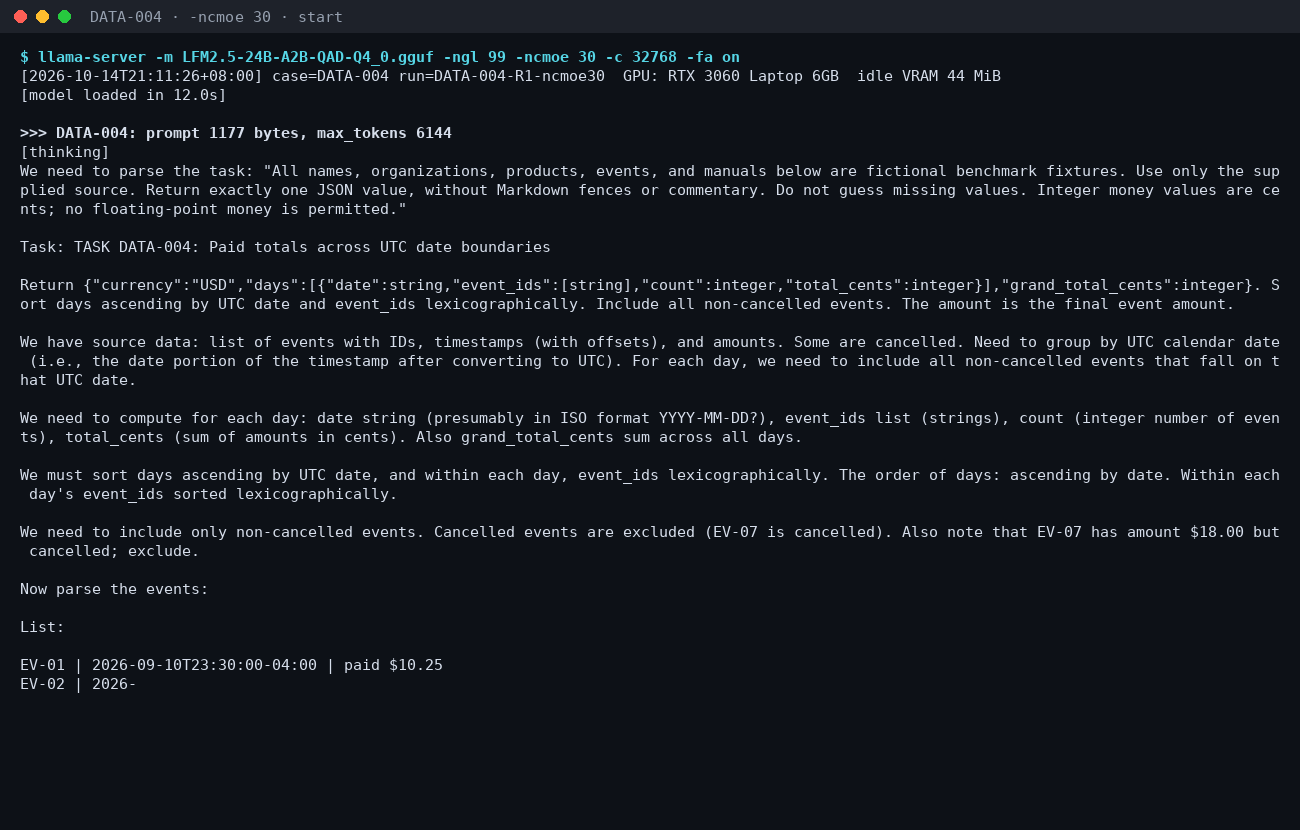
A real terminal recording of DATA-004, sped up ~16x: model load, a long thinking phase, then the JSON answer with speed and VRAM stats.
The one knob: -ncmoe 40 → 30
-ncmoe sets how many MoE expert layers stay on the CPU. The default 40 keeps all experts on CPU and uses only ~1.3 GB VRAM. At 30, ten expert layers move to the GPU: VRAM rises to ~4.5 GB, still under 6 GB, and it gets noticeably faster.
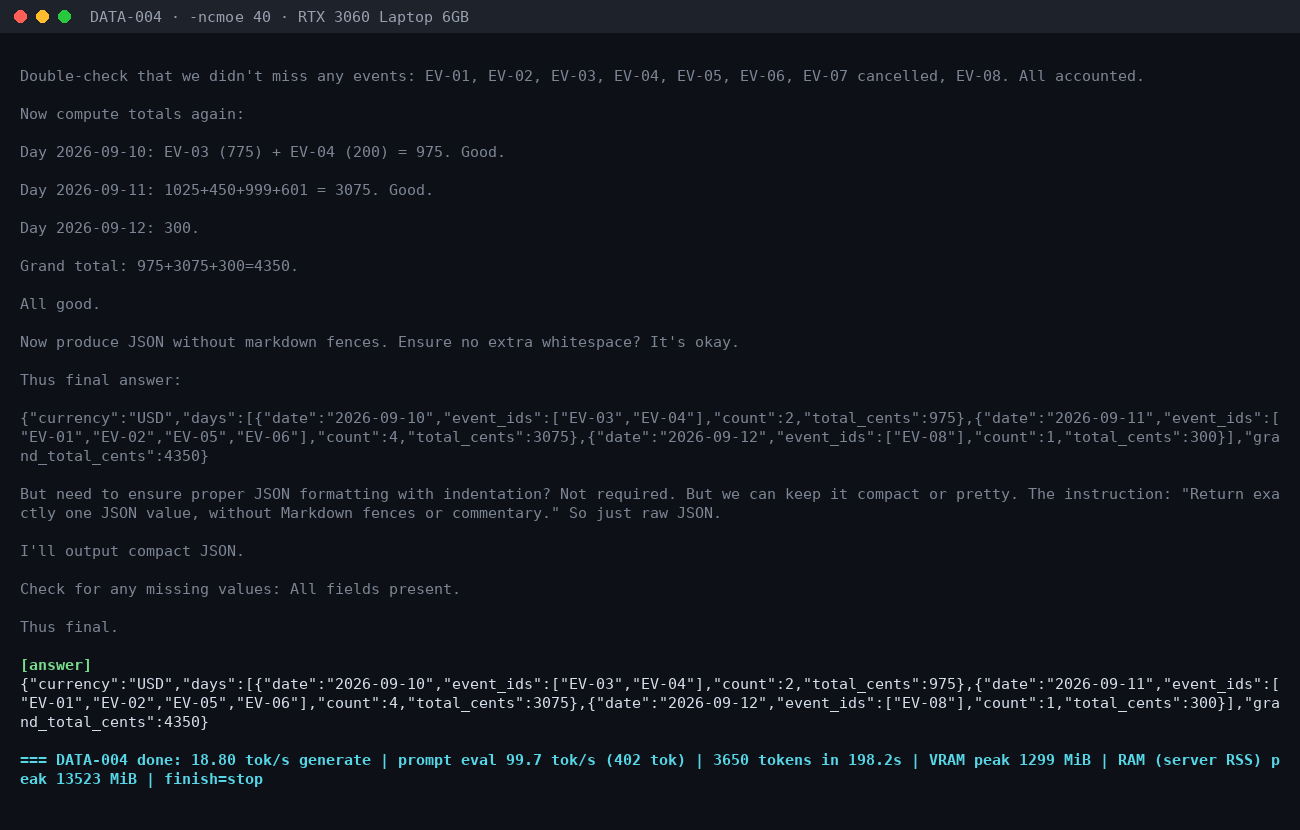
End-to-end generation speed for all three tasks (last terminal line):
            -ncmoe 40     -ncmoe 30
CODE-001    17.73 tok/s   23.28 tok/s
DATA-004    18.80 tok/s   25.99 tok/s
DOC-001     17.98 tok/s   23.80 tok/s
Peak VRAM   ~1.3 GB       ~4.5 GB
llama-bench output (RTX 3060 Laptop · Q4_0 · q8_0 KV · build 9655061, key columns only) (pure generation rate, no thinking or sampling overhead):
n_cpu_moe    test             t/s
       40   pp512   139.88 ± 3.21
       40   tg128    22.49 ± 2.23
       30   pp512   180.70 ± 2.73
       30   tg128    29.47 ± 4.96
       20   pp512    85.95 ± 0.54
       20   tg128    29.49 ± 0.39
At ncmoe 20 prompt processing drops to ~86 tok/s, so we only compare 40 and 30.
The other two tasks
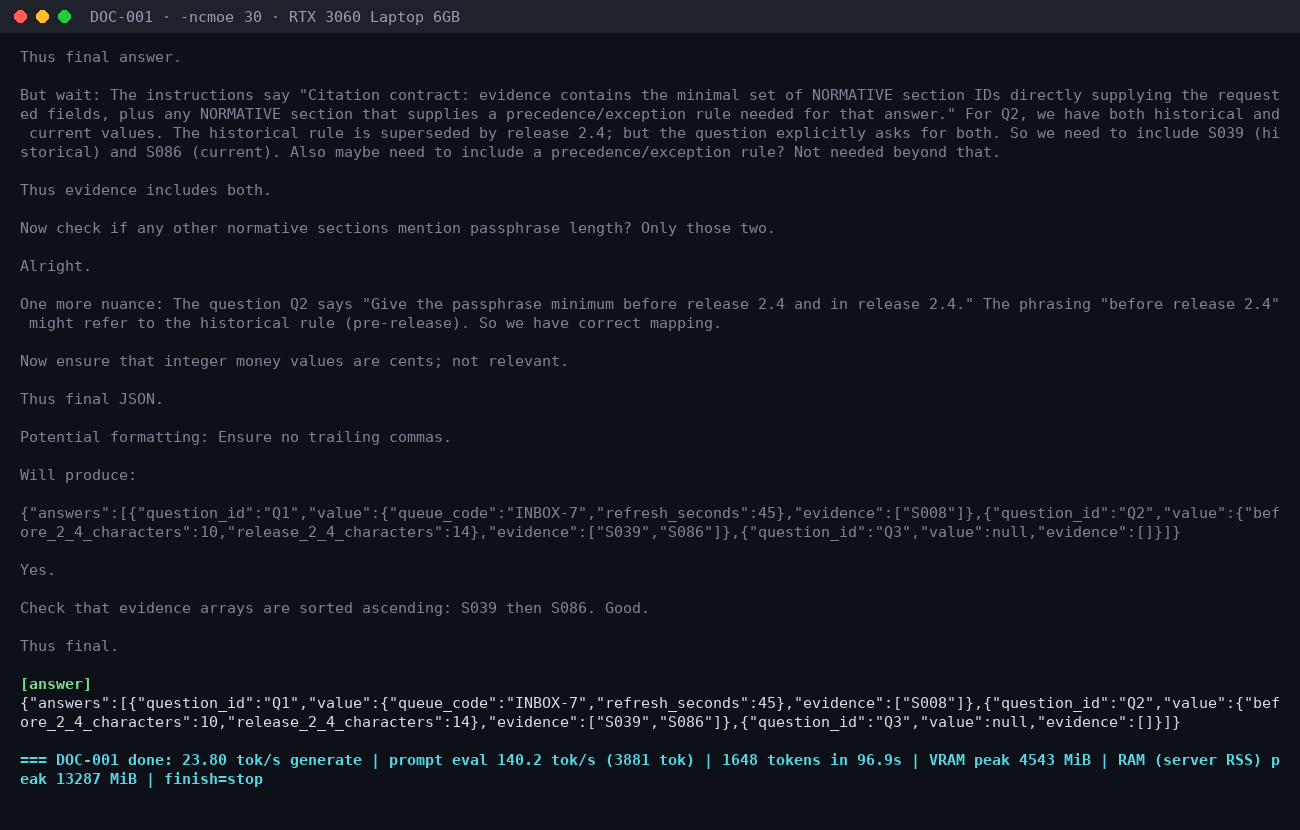
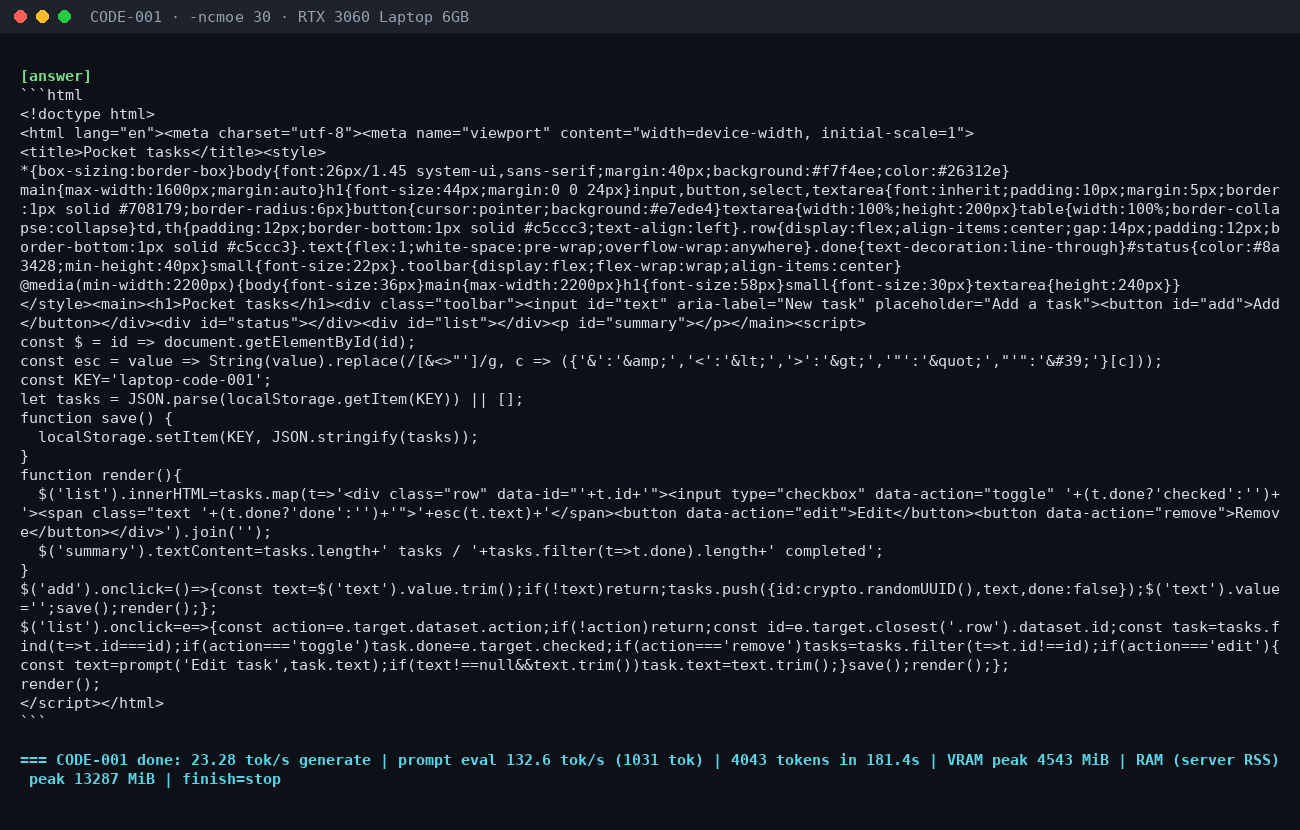
Hardware and command
Laptop: Lenovo Legion Y9000P 2022, NVIDIA GeForce RTX 3060 Laptop GPU 6 GB, i7-12700H, 64 GB DDR5
Model: LFM2.5-24B-A2B-QAD-Q4_0.gguf (official Liquid AI GGUF)
llama.cpp commit 9655061
llama-server -m LFM2.5-24B-A2B-QAD-Q4_0.gguf \
  -ngl 99 -ncmoe 30 -fa on -ctk q8_0 -ctv q8_0 \
  -c 32768 -b 512 -ub 128 --jinja --reasoning-format deepseek
Verdict
A 6 GB laptop can run a 24B model, and it is usable, as long as you have plenty of system RAM (64 GB here) for the CPU-side experts. The only knob worth touching is -ncmoe: 40 → 30 is roughly 30% faster and stays inside the VRAM budget.
Heads-up: thinking can't be turned off on this commit, so each task thinks for a minute or two before answering.